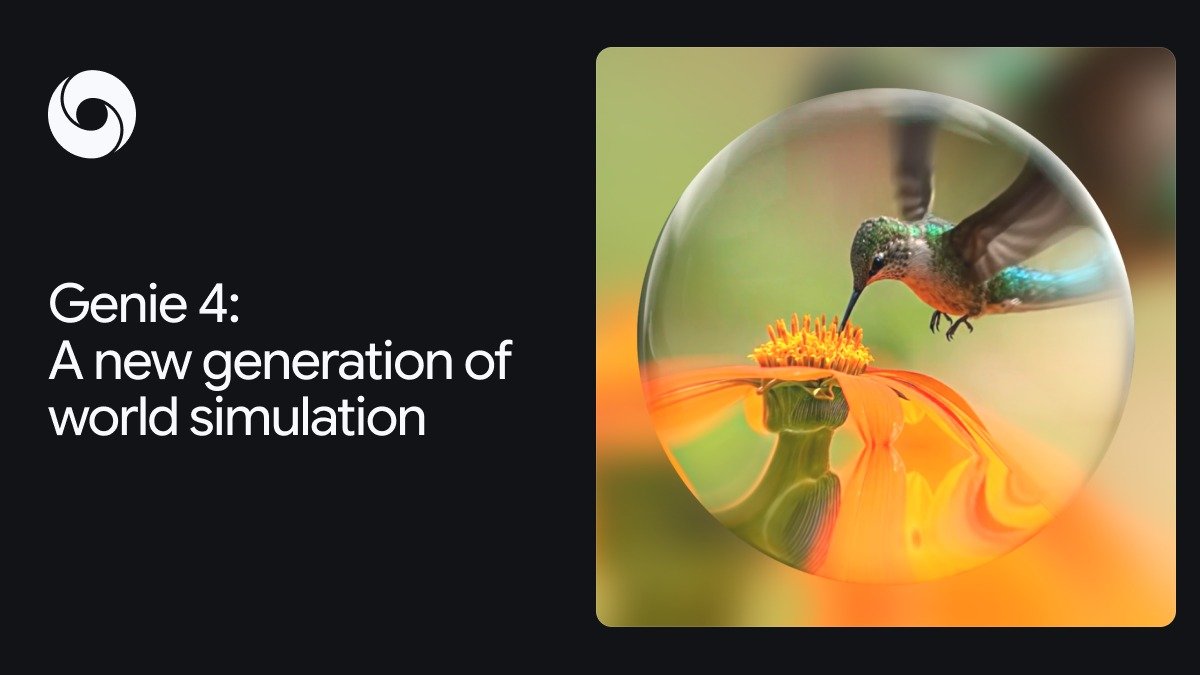
Google DeepMind has announced Genie 4, the newest version of its world model. Type a description, and Genie 4 generates a photorealistic place you can walk through with your keyboard, frame by frame, in real time. You can change the scene mid-session by typing, and for the first time in the Genie line, the world produces its own sound, including characters who talk back. It is a research preview for trusted testers for now, but it is the clearest look yet at a kind of AI that labs increasingly treat as core to their roadmaps. Here is what a world model is, what Genie 4 adds, and what it still cannot do.
Key points
- Genie 4 generates interactive, explorable worlds from text or a reference image, live, without a game engine or prebuilt 3D assets.
- New in this version: more realistic physics and people, real-time steering with natural-language prompts, and native audio with interactive dialogue.
- Gemini 3.8 Flash runs in the loop as a planner and checker, breaking goals into steps and reviewing frames to keep the world coherent.
- Access is limited to trusted testers. Google says it is coming to Google AI Ultra subscribers through Project Genie and to early-access partners in the Gemini API and Google AI Studio. No pricing yet.
- Google has not published resolution, frame rate, latency or a model card. Worlds still drift after a few minutes.
What is a world model?
A video generator makes a fixed clip. You write a prompt, wait, and get back a few seconds of footage you can watch but not touch. A world model works more like a game that is being invented as you play it. It takes your inputs, such as moving forward, turning the camera or typing “make it rain”, and predicts the next frame of what the world would look like given everything that happened before.
That last part is the hard bit. Each new frame has to stay consistent with the frames before it. If you walk away from a tree and turn back, the tree should still be there and look the same. A traditional game gets that for free because the tree exists as a 3D object in memory. A world model has no such object. It has to remember the tree from its own past output, and small errors pile up the longer a session runs. DeepMind described this problem directly when it launched Genie 3: generating a world one frame at a time is harder than generating a whole video, because inaccuracies accumulate.
Why labs care: a model that can simulate how the world responds to actions is useful for training robots and AI agents in endless varied environments, without building each one by hand. Google frames this as a step toward AGI. More practically, it is a cheap way to generate test scenarios.
What Genie 4 adds
DeepMind lists four main upgrades over its predecessor.
- Realism in physics and people. Google says Genie 4 handles aerodynamics, collisions and similar physical behavior better, and that people in scenes move and react more naturally. It calls the human simulation the biggest leap.
- Real-time steering. You can type changes while the world runs, such as new weather, a camera move, or an extra person or object. Gemini rewrites your instruction to fit the current scene, then keeps nudging the world forward between your inputs.
- Native audio. Every world generates its own ambient sound and music. Characters can hold dialogue that reacts to you and to events in the scene. Genie 3 was silent.
- Gemini as a director. Gemini 3.8 Flash watches the scene as it renders, splits a goal into steps, and checks incoming frames to confirm each step happened. If the world shifts or you intervene, it adjusts the plan.
DeepMind calls this combination an early hybrid world model: a language model handles structure, planning and narrative, while Genie handles the pixels and sound. That split matters. Pure pixel models are good at looking right and bad at keeping logic straight over time. Putting a reasoning model on top is Google’s bet for fixing the second problem without giving up the first.
The robotics angle
The most interesting demo for builders is not a pretty landscape. DeepMind paired Genie 4 with Gemini 4 Argon and Gemini Robotics to simulate Apptronik’s Apollo humanoid robot playing checkers. Argon breaks the task into steps and feeds them to Genie 4 as text captions while the simulation renders, so the scene evolves toward finishing the task. The idea is a simulator you can describe instead of build: instead of modeling a warehouse in a physics engine, you ask for one and let the planner drive a robot through it.
That is a promising direction, but it is a research demo, not a tool. A simulation is only useful for training if its physics are trustworthy, and Google itself lists complex physical interactions as an open problem.
What it still cannot do
Google is unusually direct about the limits on its Genie model page:
- Short sessions. The model supports “a few minutes of continuous interaction, rather than extended sessions.” The Verge and TechCrunch report about two minutes, double the one-minute timer in the Genie 3 based Project Genie app. Google’s own page does not state a two-minute figure, and its wording is close to what it wrote for Genie 3.
- Drift. Object permanence and visual details shift over time, especially in longer runs, after several prompt edits, or when you move around a lot.
- No real places. It cannot accurately recreate real-world locations.
- Text and audio. Legible text usually only appears if it was in your prompt, and real-time audio accuracy is still being worked on.
- Multiple agents. Modeling several independent characters interacting with each other and with you remains hard.
There is also no spec sheet. Genie 3 shipped with published numbers, 720p at 24 frames per second. For Genie 4, Google has not shared resolution, frame rate, latency, training data or price. The demo page also notes that results are illustrative and sequences shortened, and many of the showcase prompts run to hundreds of words of careful instructions. On the Hacker News thread, where the launch drew hundreds of comments, much of the skepticism focused on exactly this: object permanence, physics slips, and how responsive the controls really are.
On safety, every video and audio output carries Google’s SynthID watermark, and the model applies the same content policies as Google’s other generative models.
What it means for builders
- You cannot build on it yet. There is no public API and no pricing. If you want in, the options are the Project Genie waitlist for AI Ultra and the Gemini API early-access program.
- Think prototyping, not production. The realistic near-term uses Google’s testers describe are pre-visualization for film, quick game-concept prototypes before any engine code, and scenario generation. A few minutes of coherent world is enough for a pitch or a mood test, not for a shipped game.
- Watch the hybrid pattern. A fast language model planning and verifying while a generative model renders is a design you can reuse today with ordinary models. The same planner-checker loop works for video, image and agent pipelines.
- Expect it to be expensive. Google limited Project Genie sessions before because each session ties up dedicated hardware. A richer model with audio will not be cheaper to run, and the first consumer tier is Google’s top AI Ultra plan.
What to watch
The real test comes when people outside Google’s tester group get hands-on time. The questions are simple: how long worlds stay coherent in practice, how quickly the scene responds to input, and whether the dialogue holds up. Pricing for the Gemini API version will decide whether developers treat Genie 4 as a tool or a demo. And with world models now a priority at several labs, Google will be judged on what it publishes, not only on how good the clips look.