Fireworks Research introduced Ember-1, a specialized model built on Moonshot’s Kimi K3 that aims for K3-class quality at about 40% fewer tokens. It is not a new base model. Fireworks post-trained K3 so it keeps the reasoning that matters and drops the rest — then checked that claim on public benches, live customer A/B traffic, and its own coding workloads.
The pitch matters for agent builders: reasoning models often spend most generated tokens on internal thinking, and multi-turn agents re-send that history every turn. Shorter traces cut billable tokens and context growth. Ember-1 is shipping as a Research Preview on Fireworks Serverless with a two-week access window; permanence depends on demand.
Image credit: Fireworks
Key points
- What it is: A Fireworks Research specialized model on Kimi K3, trained for shorter reasoning — not a from-scratch base model.
- Headline claim: K3 quality with ~40% fewer tokens (vendor: 35–50% shorter reasoning across their benches; ~35–39% total token reduction in customer A/B).
- Why not “turn effort down”: Fireworks says lowering K3 reasoning effort gave up too much quality; they trained for efficiency instead (50+ training runs, 200+ evals on Serverless Training; no customer data used).
- Vendor benches vs K3-max: Terminal Bench 2.1 82.0% vs 80.9% (−51.9% tokens); SWE-bench Verified 92.2% vs 93.2% (−15.5%); DeepSWE 1.1 75.2% vs 66.4% (−23.7%); plus SWE-Interact and τ-2 Airline — all vendor-reported.
- Deployability: Research Preview on Fireworks Serverless alongside base K3; two-week serverless access; may become permanent based on community demand. Training support for custom Ember-1 variants is also launching.
- Pricing caveat: Cost charts use public Kimi K3 rates ($3/M uncached in, $0.30/M cached, $15/M out). Ember-1 itself is not separately priced in the post.
- Honesty: Every quality/token figure is vendor-reported. Independent replication is not shown. A preview window is a real product caveat for production budgets.
What shipped
Ember-1 is the first model in a planned series from Fireworks Research under a “specialized intelligence” theme: take a strong open model, train it for a concrete efficiency goal, serve it on Fireworks.
According to the company:
- Users wanted K3’s coding strength without paying for very long reasoning traces.
- Simply reducing K3’s reasoning effort lost too much quality.
- Training on math, coding, instruction following, conversation, search, tool use, and software engineering — including multi-turn agent loops — taught the model to cut unproductive reasoning while keeping useful self-reflection.
Ember-1 is available as a serving option next to base Kimi K3. Fireworks is also launching training support so enterprises can build custom, token-efficient Ember-1 variants on their own data.
Why reasoning tokens matter for agent builders
On a single request, long chain-of-thought is already expensive. In multi-turn agents it gets worse: each turn typically re-injects prior reasoning into context, so cost and latency grow roughly with the square of turns if traces stay long.
Fireworks’ framing: much of K3’s emitted reasoning is longer than the task needs, and the excess can be removed without changing the answer — if the model learns which reflection to keep. That is a different product bet than “use the low-effort knobs and hope.”
For builders running automated coding or tool-using agents, the useful question is not “is the Pareto chart pretty?” It is: on my tasks, do success rate and failure modes hold when total tokens drop ~35–40%?
Numbers (vendor-reported)
Treat every figure below as Fireworks’ own evaluation, not an independent audit.
Industry benches (Ember-1 vs K3 max) — token % and USD deltas are Fireworks’ arithmetic using public Kimi K3 API pricing:
| Benchmark | N | K3 max | Ember-1 | Ember-1 vs K3 max |
|---|---|---|---|---|
| Terminal Bench 2.1 | 89 | 80.9% | 82.0% | −51.9% tokens / −$23.1 |
| SWE-bench Verified | 500 | 93.2% | 92.2% | −15.5% tokens / −$68.1 |
| SWE-Interact | 75 | 21.3% | 20.0% | −32.5% tokens / −$60.8 |
| DeepSWE 1.1 | 113 | 66.4% | 75.2% | −23.7% tokens / −$126.9 |
| τ-2 Bench Airline | 50 | 64% | 66% | −5.9% tokens / −$0.3 |
Across those suites Fireworks also compares K3 at low/high/max effort and says Ember-1 sits on or near the quality-vs-cost Pareto frontier while strictly dominating K3-low.
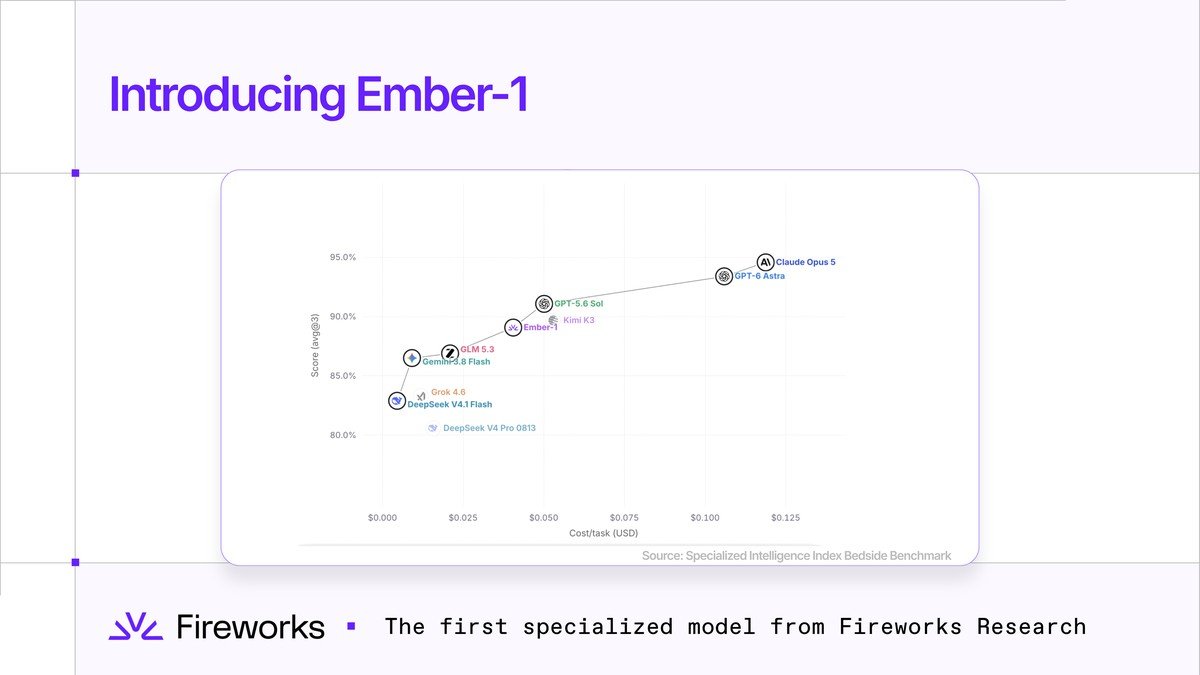
Specialized Intelligence Index — Bedside Bench: Fireworks reports Ember-1 on Doximity’s physician-validated Bedside Bench (500 clinical cases) as a new cost/task Pareto point among open and closed models they plotted (including GPT-5.6 Sol, GPT-6 Astra, and Claude Opus 5). That chart is industry-specific; do not generalize it to coding agents without your own evals.
Customer A/B (two production coding workloads): Fireworks reports ~35% fewer tokens per task at comparable quality; one published arm shows score 0.753 vs 0.751, steps 21.4 vs 23.8, output tokens 29.9K vs 49.3K, reasoning-token reduction 71.3%, total token reduction 39%. One customer, per Fireworks, moved Ember-1 into live production after the test.
Internal: Fireworks says its own developers did not notice a silent swap on internal coding traffic while token use fell — an anecdote, not a public metric.
Deployability and limits
- Surface: Fireworks Serverless Research Preview alongside base Kimi K3.
- Window: Two-week serverless access for research releases; permanence tied to community demand.
- Customization: Training support for Ember-1 variants on customer data is launching with the release.
- Not claimed: A separately published Ember-1 price list in the announcement — cost plots reuse K3 public rates.
- Not shown: Third-party replication of the benches or A/B results.
What builders should do
- Shadow A/B on your agent coding traffic — Hold out a slice of real tasks. Compare task success, retry/failure rates, and total tokens (not just completion length). Vendor averages will not match your harness.
- Do not budget production solely on a Research Preview — Two weeks and demand-gated permanence means treat Ember-1 as a trial endpoint until Fireworks commits to a durable SKU.
- Prefer Ember-1 over “K3 effort=low” only if quality holds — That is Fireworks’ stated reason for training. Verify it; the low-effort baseline is the honest control.
- Watch multi-turn context growth — The savings thesis is strongest where prior reasoning is re-billed every turn. Single-shot chat may see smaller wins than agent loops.
- If you need workload-specific efficiency — Note the training-support launch; specialized fine-tunes are the company’s longer bet beyond one shared Ember-1 checkpoint.
Key takeaways
- Ember-1 is Fireworks’ first specialized model: Kimi K3 post-trained for shorter reasoning, marketed as ~40% fewer tokens at similar quality.
- The strongest builder hook is agent/coding cost, not a new capability ceiling.
- Published numbers are vendor-reported; customer A/B and Bedside Bench Pareto claims need your own validation.
- Availability is a Research Preview with a two-week serverless window — useful for trials, fragile as a sole production dependency.
- Custom Ember-1 training support is part of the same launch story.
Sources
- Introducing Ember-1 — Fireworks (primary)